Genvizu

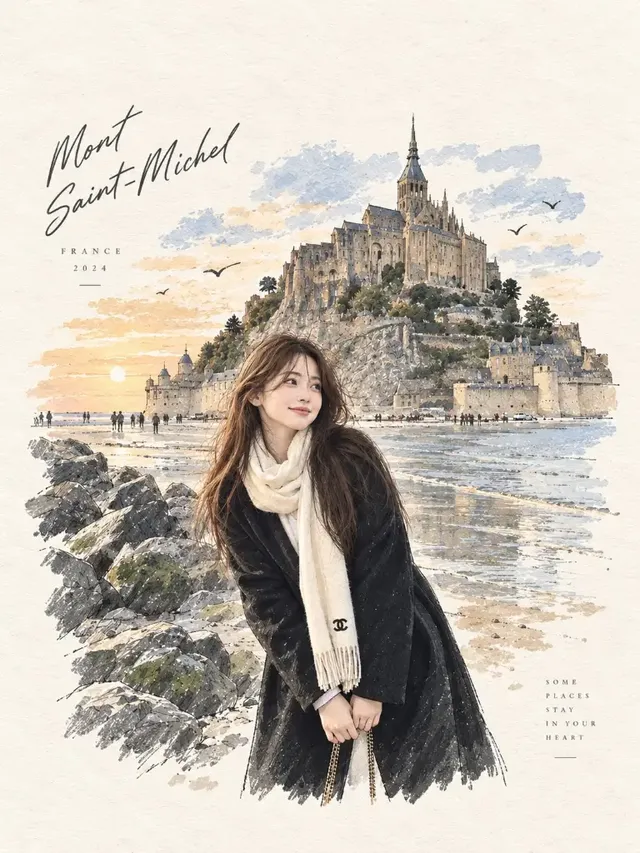
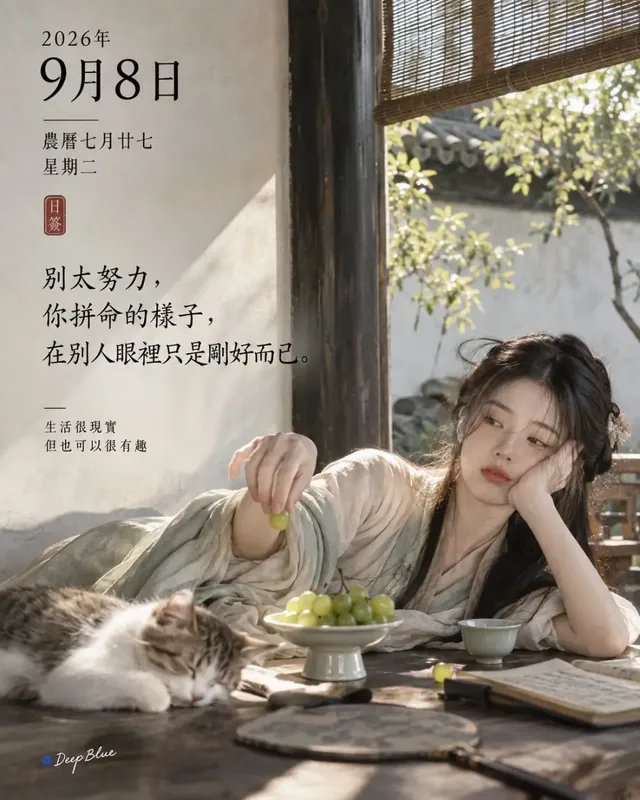
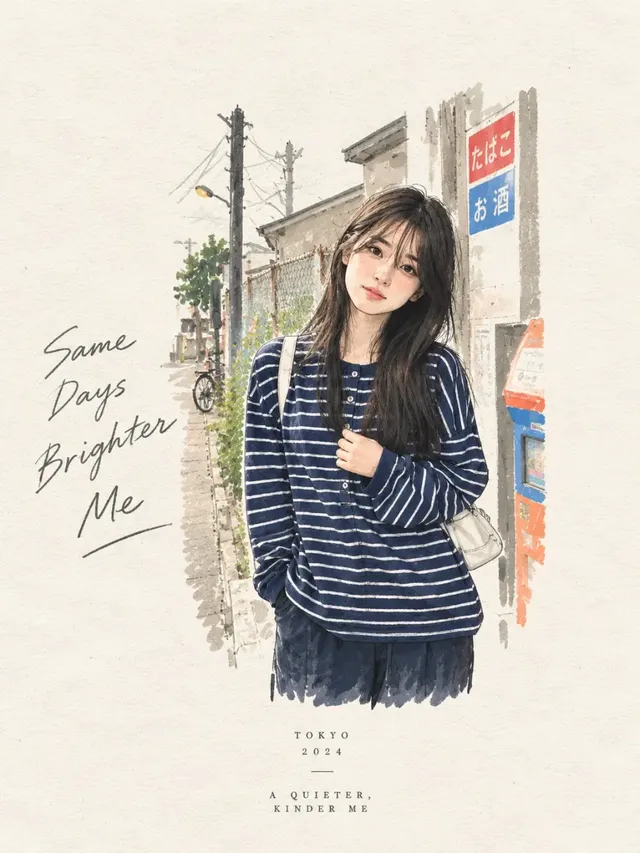
AI creations made with GPT Image 2

OpenAI

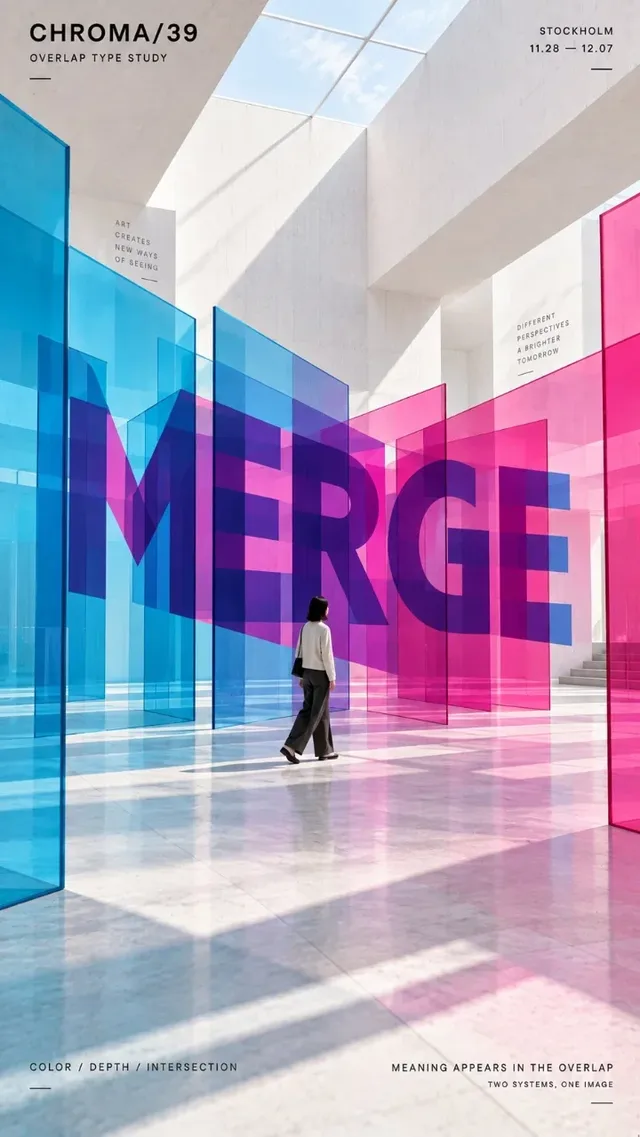
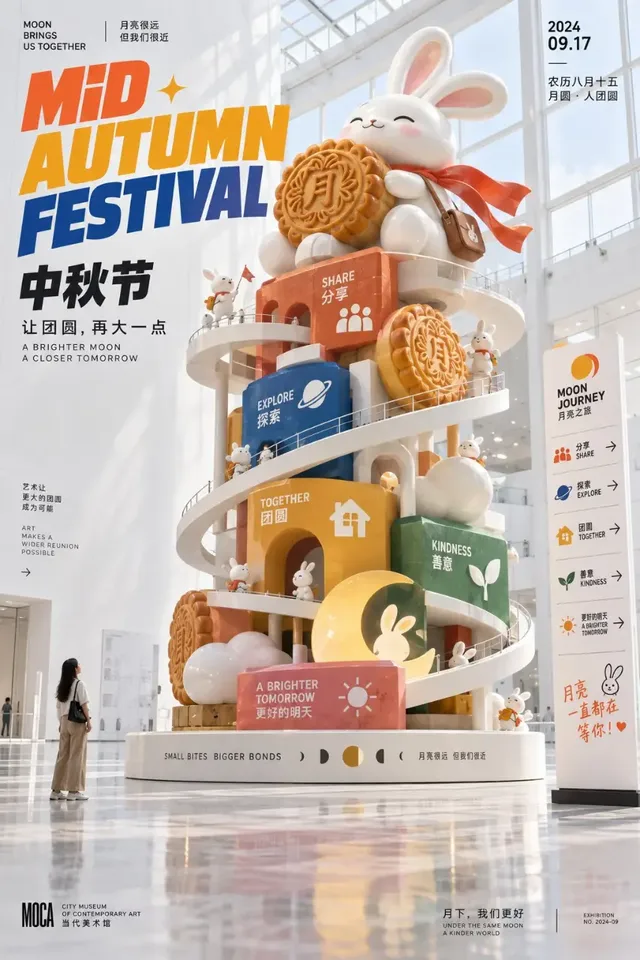
GPT Image 2 is OpenAI's image model on Genvizu, reachable as text-to-image and as image-to-image. Choose it when the picture itself has to carry readable typography: posters, packaging, slides and UI mockups. One run returns a single image, because the upstream endpoint exposes no batch parameter. Resolution is selectable at 1K, 2K or 4K, ten aspect ratios are selectable, from 21:9 down to 9:16 and including 4:5 and 5:4, prompts run up to 20,000 characters, and the image-to-image channel accepts up to 16 reference images.

Verified on 2026-09-10

Start free · no credit card

Best for

  • Layouts where exact words must appear in the image: poster headlines, packaging copy, slide titles, UI labels.
  • Long, structured briefs — the prompt limit is 20,000 characters, so composition, palette and typography can each get their own paragraph.
  • Portrait and landscape social crops: the selectable set has ten entries and includes 4:5, 5:4 and 21:9 alongside the common photo ratios.
  • Editing an existing picture against several references at once, up to 16 reference images in the image-to-image channel.
  • Briefs written in Chinese or any other language — this model has no English-only requirement.

Not for

  • Getting four variations from a single click — one run returns one image, so several candidates means several runs.
  • Reproducing an earlier result exactly: the upstream endpoint takes no seed, so the same prompt can drift between runs.
  • Guaranteed identity lock on a specific person or product. Reference images steer the result, they do not reproduce a subject exactly.

Specifications and limits

FieldValue
ProviderOpenAI (routed through Genvizu)
InputText prompt; optional reference images in the image-to-image channel
Output1 image per run; a higher batch count means more runs, each billed separately
Resolutions1K / 2K / 4K (2K is the default)
Aspect ratios1:1, 3:2, 2:3, 4:3, 3:4, 5:4, 4:5, 16:9, 9:16, 21:9 (ten in total)
Prompt languageAny language; English is not required
Prompt limit20,000 characters
Reference imagesUp to 16, image-to-image only (text-to-image accepts none)
SeedNot exposed upstream — runs are not reproducible
BillingPer image, and higher resolution tiers cost more (see the pricing page)
Failed runsRefunded automatically

Prompt examples

Poster headline that has to read correctly

Prompt

Vertical event poster, 2:3.
Headline "NIGHT MARKET" in bold condensed sans, upper third, tight letter spacing.
Subtitle "Fri 20:00 - Pier 4" in small caps directly beneath, thin rule between them.
Scene: warm street-food stalls at dusk, shallow depth of field, steam catching the light.
Palette: deep teal background, amber highlights, off-white type.
Leave the lower quarter uncluttered for a sponsor row.

Quote the exact strings and state their hierarchy. Naming the empty zone is what keeps the layout usable when you add logos later.
Packaging mockup with legible label copy

Prompt

Product photograph of a matte kraft coffee bag standing on a concrete surface, 1:1.
Label: "SINGLE ORIGIN" as the top line, "ETHIOPIA / GUJI" larger beneath it, "250 g" bottom right in small type.
Soft window light from the left, long soft shadow to the right.
Palette: kraft brown, ink black, one signal orange accent.
Sharp label edges, no motion blur, no reflections over the text.

Name each label line separately instead of asking for "some product text", so every string you have to read is written out. The no-reflection clause keeps highlights off that text.

Reference-driven edit (image-to-image)

Prompt

Keep the product from the reference image unchanged in shape, label and colour.
Replace the background with a sunlit bathroom shelf, small eucalyptus branch on the right.
Match the reference lighting direction; add a soft cast shadow under the bottle.
16:9, editorial still-life look, no added text.

Say explicitly what must not change. The image-to-image channel accepts up to 16 references, so several angles of the same product can go in together.

How it compares

Grok Image 2

Also aimed at in-image typography, but text-to-image only, with no resolution tiers and no reference images. Pick it for quick poster exploration; come back here when you need 4K or an edit against references.

Nano Banana 2

Takes up to 14 reference images and also offers 1K/2K/4K. Pick it when the job is reference-heavy editing rather than typography.

Midjourney 8.2

Returns four images per run and caps prompts at 1,024 characters. It requires English prompts, and its output is commercially restricted by Midjourney terms.

Examples from the gallery

Common failures and fixes

Long strings in the image come back misspelled or with dropped characters.

Put every string in quotes on its own line, keep each below roughly six words, and state its role (headline, subtitle, footnote). Verify the rendered text before publishing — no model guarantees typography.

The composition ignores an aspect ratio you set in the prompt.

Aspect ratio is a panel parameter, not prompt text. Change it in the generator panel; a ratio written into the prompt is treated as description.

A 4K pass across many drafts burns through the balance faster than expected.

Higher resolution tiers are billed per image, so cost scales with the number of runs. Draft at 1K, then re-run only the winning prompt at 4K.

A reference image barely influences the result.

You are probably on the text-to-image channel, which accepts no references. Attach the image in the generator so the run switches to the image-to-image channel, and describe which attributes must be preserved.

Frequently asked questions

How is GPT Image 2 billed on Genvizu?

Per generated image, with higher resolution tiers costing more than lower ones. The current tiers are listed on the pricing page, and the generate button shows the exact cost of the run you are about to start before you confirm it.

Does GPT Image 2 accept reference images?

Yes, in the image-to-image channel, up to 16 reference images. The text-to-image channel accepts none; attaching a reference in the generator is what switches channels.

Do I have to write prompts in English?

No. GPT Image 2 has no English-only requirement on Genvizu, unlike the Midjourney models. Strings that must appear inside the image should still be quoted exactly as you want them rendered.

How many images does one run return?

One. There is no n parameter upstream, so several variations means raising the batch count in the generator, and each image is billed separately.

What happens if a generation fails?

Failed generations are refunded automatically — the amount deducted for the run returns to your balance.

Sources